
Prequel · The death of Netscape
On 6 April 2000, Joel Spolsky published an essay on his blog. The story starts with Netscape. In early 1998, Netscape had decided to tear Navigator down and start over — the old code was a mess, the engineers thought it was beyond saving, so why not begin from zero. The rewrite took the better part of three years. In those three years, Internet Explorer, bundled free with Windows, ate the market inch by inch; by the time Netscape 6 finally limped out at the end of 2000, they found the first browser war was already over, and there was no battlefield left.
Netscape itself had already sold to AOL partway through those three years. Netscape 6 was slow and riddled with bugs, and what users remained left faster than ever; in 2003 AOL disbanded the entire browser team, and on 1 March 2008 the last version lost support. The onetime ruler of the market — ten years earlier, it had been synonymous with the browser itself — was simply gone.
Spolsky called the decision “the single worst strategic mistake that any software company can make” and then wrote the sentence that has been quoted for twenty-six years since:
When you throw away code and start from scratch, you are throwing away all that knowledge.
In plain terms: don't rewrite from scratch lightly, because what you throw away isn't just code — it's the years of knowledge that accumulated inside it.
He also explained, in passing, why programmers always want to rewrite: “It's harder to read code than to write it.” His example is a two-page function whose only job is to display a window, yet it's covered in inexplicable patches: an extra check here, a detour of special-case handling there, a LoadLibrary call that's ugly as sin, and nobody can say why any of it is there.
Not one of those patches is spare, Spolsky says — each one is a real incident that happened: some machine had no Internet Explorer and the install failed, so a check was added; the program crashed when memory ran low, so a handler went in; a user yanked the floppy disk out mid-write, so another one did; and that ugly LoadLibrary is what keeps the program running on old versions of Windows 95. Peel any one of them off, and some user in some corner falls over again.
Twenty-six years on, the floppy disks are gone, Windows 95 is gone, Netscape is gone. The sentence is still here. And in 2026, it met the toughest opponent it has faced in twenty-six years.
1. What exactly is hiding in old code
The idea is easiest to misread as:
Old code is good code, so don't touch it.
Not at all. Nowhere does Spolsky say the old code is good — he says the old code has things hidden in it. As for what's hidden, I think there are at least four layers.
Layer one: explicit business rules
if customer.country == "US":
    ...
This layer is the easy one. A human reads it at a glance; so does an AI. These are the rules already written in the product docs, just stored somewhere else.
Layer two: the knowledge of historical bugs
if amount == 0 and payment_provider == "XYZ":
    retry_after = 2
A new programmer will most likely say: why does a zero amount get special treatment? Delete it.
But maybe it's there because back in 2017 the XYZ payment gateway had a weird race condition: zero-amount requests would occasionally get stuck, and waiting two seconds before retrying fixed it. What the code is really saying is: “we've already stepped in this hole.” The person who stepped in it may have left the company years ago. The hole is still there, and these two lines are all that's left standing guard.
Layer three: compatibility knowledge
This layer is more dangerous still:
- some version of some browser
- some old version of a database
- some customer's home-modified API
- some region's different date format
- some hardware device that implemented the standard wrong
- some third-party API whose actual behavior has nothing to do with its documentation
These compatibility details are often not fully documented in the specification, but they are captured in the code. They live in the if, the else, the workaround, the retry, the fallback, and the compatibility shim. Most of the patches Spolsky is talking about are sewn onto this layer.
Layer four: the knowledge that isn't in the code at all
This is the biggest trap of the AI era. For a system that has been running for years, the real specification is the sum of all of this:
Code
+ Tests
+ Git History
+ Issue Tracker
+ Production Logs
+ Customer Complaints
+ Dirty Data in the Database
+ What's in Some Employee's Head
Source code is one item on that list. So even if you hand a coding agent the entire repo today, that doesn't mean it has the system's full knowledge — it has the first three layers, plus whatever sliver of the fourth happened to get written into comments and tests.
2. The opponent, twenty-six years later
Which raises the obvious question at this point: how strong have the models actually gotten, that anyone would dare to cross the line Spolsky drew?
The answer arrived just days ago. On 1 September, Anthropic released Claude Fable 5.1; on 3 September, OpenAI released GPT-6 Astra. Neither launch spent a minute on chat. Both were about agentic coding: hand the model a task and let it run to the end in a terminal on its own. The numbers side by side:
| Benchmark | Fable 5.1 | GPT-6 Astra | Fable 5 | GPT-5.6 Sol |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 55.8% | 57.7% | 42.0% | 37.3% |
| Terminal-Bench-Science 0.1 | 52.6% | — | 24.7% | 22.4% |
| DeepSWE v1.1 | 67.4% | 74.1% | — | 72.7% |
| FrontierCode 1.1 Extended | 64.9% | 64.5% | — | — |
| Humanity's Last Exam (with tools) | 65.0% | 57.2% | 63.8% | — |
Whether Fable 5.1 or Astra is the stronger model doesn't strike me as a question worth much: with every model company now gaming benchmarks, deliberately or not, and each publishing only the rows that flatter it, benchmarks themselves tell you less and less — and the gap between benchmark scores and what you actually experience using these models has grown wide enough to deserve a blog post of its own someday.
So this table is half an answer at most. A benchmark is an exam — someone wrote the questions and someone wrote the answers; nobody ever wrote them for rewriting a system that has run for twenty years. The other half of the answer is in a handful of real cases from the past four months — every one of which, note, happened before either of these models shipped:
| Case | Migration | Scale | Time | Verification |
|---|---|---|---|---|
| Bun / Anthropic | Zig → Rust | 535,496 lines of Zig | 11 days, up to 64 Claude agents in parallel | 100% of the existing CI suite green before merge; 19 regressions found and fixed after launch; Bun 1.4 shipped |
| TensorFlow → JAX | Real YouTube models: thousands of lines, hundreds of layers | Months → weeks, 6.4–8× faster than by hand | Static analysis + gradient ascent to find the maximum error between old and new layers | |
| Wiz | Python → Go (pypdf) | ~50k lines → 18,413 lines | ~20 hours | 500 pathological PDFs + a production feature flag diffing against the old implementation |
| Anthropic Labs | Python → TypeScript | 165k lines of TypeScript | One weekend | Hundreds of agents, 8 phase gates, 3 rounds of adversarial review, every command's output diffed against the Python original |
3. Bun: 11 days, 535k lines of code and $165k
The Bun story is far more aggressive than “Claude helped me refactor a few tens of thousands of lines.”
Jarred Sumner started with 535,496 lines of Zig (comments excluded). His own estimate was that a small team intimately familiar with the whole codebase would need about a year.
What actually happened: one person in charge, plus a Claude model that hadn't been publicly released yet, plus Claude Code's dynamic workflows. Work started on 3 May and finished on 14 May. Eleven days.
The details are all in Bun's official write-up:
- Before touching any code, Sumner spent about three hours talking with Claude about how Zig's patterns should map onto Rust, and Claude serialized that discussion into a
PORTING.md. They also ran a lifetime analysis across the whole codebase. Three files were ported as a trial run before opening the floodgates. - Every task had the same fixed structure: one implementer, two or more adversarial reviewers, one fixer. Around 50 dynamic workflows ran across four parallel worktrees, with as many as 64 Claude instances running at once — 6,502 commits in total, and 1,300 lines per minute at the fastest.
- The hard requirement was that Bun's existing test suite pass 100% on every platform — roughly 60,000 test files and more than 1.3 million
expect()calls. Number of tests skipped or deleted: zero.
Anthropic later disclosed the bill in a blog post: 5.9 billion uncached input tokens, 690 million output tokens, plus 72 billion cached input reads — roughly $165,000 at public API pricing. After the merge, 19 known regressions surfaced in production; Anthropic says all of them have been fixed.
And the result wasn't a prototype. On 20 August, Bun 1.4 shipped as the first stable release running entirely on Rust; 1.3.14 became the last Zig version.
Which means the old economic model:
3 Engineers × 1 Year
can suddenly become, roughly:
1 Expert + 11 Days + $165k of Inference + CI / Fuzzing / Review
That is not a 20% productivity improvement. That's an order-of-magnitude change.
Not everyone bought it, of course. Zig's creator Andrew Kelley called the rewrite “unreviewed slop,” and his question is actually a sharp one: how is a test suite written for Zig sufficient to validate a million lines of Rust that nobody has read? I'll leave that question unanswered for now. Read on and you'll find it is the same question Spolsky was asking.
4. Wiz: 99% and 1%
Wiz wanted to move pypdf to Go.
This project ticks nearly every one of Spolsky's danger conditions: Python; more than 20 years old; around 50,000 lines; PDF is a format stuffed with bizarre historical compatibility; and every piece of software in the world that produces PDFs has its own reading of the standard. What pypdf has spent those twenty years doing is learning those quirks, one by one.
In theory, this is exactly the kind of project where you say: “never rewrite this, it's twenty years of hidden knowledge all the way down.”
Claude did it anyway. In Wiz's case study, the engineers spent about 20 hours — 10 developing, 10 testing — turning 50,000 lines of Python into 18,413 lines of Go. They assembled a test set of 500 pathological PDFs collected specifically for this. All 500 passed.
So Spolsky's rule no longer holds?
No.
They put the new library into production behind a feature flag, running it side by side with the old Python implementation and comparing outputs one by one: 99% matched.
Great. But there was still 1%.
And that last 1% showed up only in real customer data — not one of the 500 hand-picked pathological samples had covered it. Wiz went through multiple rounds of diagnosis driven by real production inputs (five to ten iterations per problematic file), and in the end found and fixed 20 to 30 distinct classes of issues.
This is the 2026 edition of Spolsky's sentence:
2000: your old code is covered in patches, each one a fixed bug, you don't know what they cover, but you can't pull them off.
2026: Claude ported a 20-year-old PDF parser in 20 hours, all 500 pathological tests passed, and production still had that last 1% hiding in it — the patches the AI was able to read out of the old code all made the trip; the ones never written into the code still had to be bumped into by customers, one at a time.
So AI didn't eliminate unknown unknowns. It just made rediscovering those unknowns a great deal faster.
5. My own version: Web Update Monitor
Before the conclusion, one example of my own.
Web Update Monitor started out as what I thought was a small program, so I wrote it straight in JavaScript (it still isn't open to the public, because I have never gotten around to turning it from a single-tenant, single-user system into a multi-tenant, multi-user one — I can already picture how many tests that means writing, and how many edge-case bugs it means hitting). Around twenty thousand lines in, I hit a bug JavaScript itself couldn't catch — a field that was undefined on one particular path, carried deep into the program before anything blew up, and it took forever to trace back to the source. I decided to move the whole thing to TypeScript. That step went remarkably smoothly — and looking back, the reason is simple: the compiler was the referee. The old code was right there, and every type that didn't line up, tsc pointed at directly; the AI only had to work down the error list one by one.
Later the components kept growing. State was scattered everywhere, a single DOM change had to be synced by hand in several places, and fixing one spot meant missing another. I decided plain TypeScript was no longer enough and went for a big-bang migration: move everything to React + Vite. Martin Fowler has a line, quoted endlessly, that might as well have been written about this exact move:
If you do a big-bang rewrite, the only thing you're guaranteed of is a big bang.
This time there was nothing to check against. The old program's behavior lived in DOM manipulation and in my own head; there was no test suite, and nothing at all that could tell the AI where the new version differed from the old one. The result, after burning through several of Claude Max's five-hour limits, was a mess — all of it discarded.
But the pain points were still there, and after a stretch of going back and forth, I made a second attempt: GPT-5.5 Thinking (its instruction-following is a good deal better than Opus 4.8's), plus Goal mode, plus the most important piece — Playwright as its eyes, so it could open the page, click the buttons, and look at the result itself instead of relying on my description of what it “should look like”; the prompts were far more elaborate than the first time, too. That finally got it across.
Except that the thirty-odd PRs that followed were almost all about fixing problems the migration had introduced.
Three migrations, one codebase, three completely different outcomes. The difference wasn't the model; it was whether there was something to check against: the first time it was the compiler, the third time it was Playwright, the second time there was nothing. As for those thirty-odd PRs — that was my 1%.
6. What changed, and what didn't
Put these cases side by side and the conclusion looks obvious: rewriting is no longer forbidden. But look at what the three most successful cases — Bun, Wiz, Google — have in common:
        Legacy Implementation
                 ↓
         Reference / Oracle
                 ↓
     ┌───────────┼───────────┐
     ↓           ↓           ↓
   Tests     Compiler   Production Traces
     ↓           ↓           ↓
          AI Translation
                 ↓
           Target System
                 ↓
         Differential Check
In other words, they are not:
Old Code → Delete → AI Guesses a New One from the README
but:
Old Code → Becomes the Specification → AI Keeps Converging on It
The most extreme version is Anthropic Labs' weekend: after hundreds of agents had turned a Python tool into 165,000 lines of TypeScript, the final gate was diffing the output of every single command against the Python original — not “the tests look about the same,” but, for every input x:
Output_Python(x) ==? Output_TypeScript(x)
That's differential testing. The old implementation isn't the thing being deleted; it's the referee.
When Anthropic lists why migrations suit AI so well, two of the reasons are precisely these: the old code serves as a great spec for the model; and there's a built-in referee — the compiler and the test suite tell you where you're wrong. That is very nearly Spolsky's insight, repackaged as agentic engineering.
Before agentic engineering, this approach already had a name. In 2004, Martin Fowler — the author of Refactoring — published Strangler Fig Application on his blog, named after a plant: the strangler fig (Fig. 1). Birds carry its seeds high into a host tree, where they sprout on a branch and send roots down along the trunk; once the roots reach the soil they thicken, wrapping the trunk a ring at a time. The enclosed tree is starved of light and can no longer grow; years later it has died and rotted away, and what stands in its place is a hollow fig — which never cut the tree down, only grew out of it.
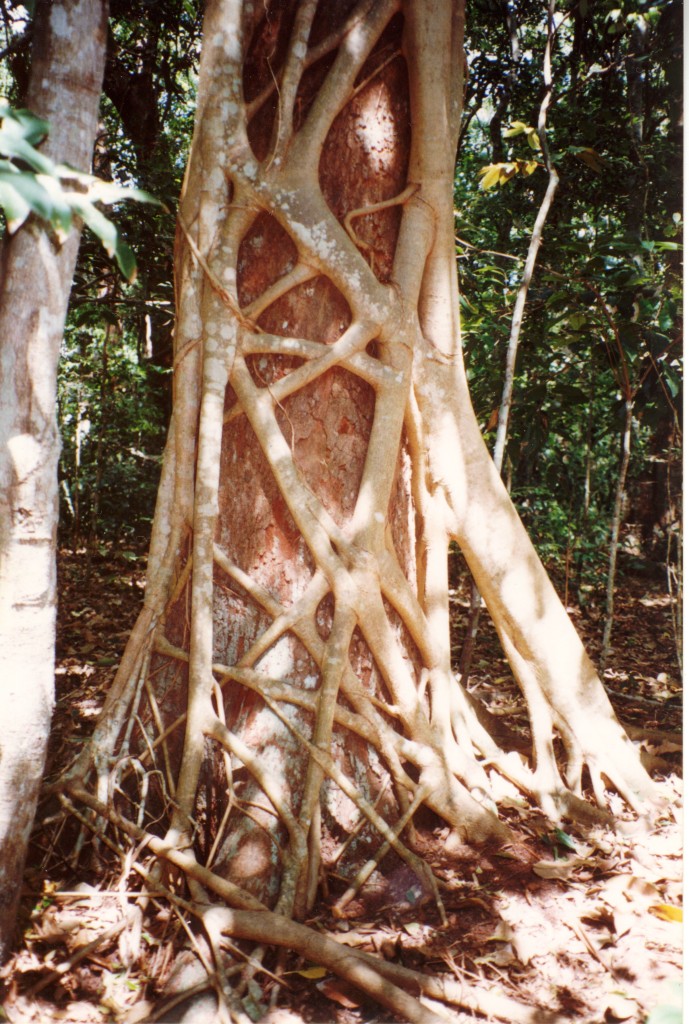

Back to software: the tree being wrapped is the old code, years in service and covered in patches; the strangler fig is the newly written version. It does not delete the old code all at once and swap in the new — it grows out of the old code. First a thin entry layer goes in front of the old code, and every request still arrives there as before. Then you pick one feature, rewrite it in the new code, route that one feature's traffic across, and switch off the corresponding part of the old code — everything else keeps going through the old code. Feature by feature it moves over; every step can ship and every step can be rolled back, and the old code keeps running alongside the whole time, always there to compare against. When the last feature has crossed, the old code is deleted, and what is left standing is the new one.
His starting point was a career's worth of rewrites of critical projects: every one looked like “the new one just does what the old one does,” every one turned out far more complicated than expected, and the most dangerous part was always the cut-over date — everything switching over on a single day. So his answer was the strangler fig: don't wait until the new version is finished and then switch everything over at once. He would rather accept a period of transitional architecture in exchange for earlier value and far lower risk.
In a diagram, the two approaches look like this:
And the second approach has no moment where the whole company's fate rides on a Saturday night. The strangler fig is safe precisely because the old code stays alive — it is both the specification and the referee. Wiz running the new and old implementations side by side behind a feature flag is exactly this.
Back to the four layers from section 1. The first three layers live in the code, and the AI can read them; as long as the old code stays in the loop as the oracle, a differential check can squeeze them out layer by layer — which is exactly how Bun got to 100% before merge. The fourth layer isn't in the code. The AI can't read it, the tests can't test it, and the only place it can surface is production, when a customer bumps into it — which is exactly where Bun's 19 post-launch regressions and Wiz's 1% came from. Andrew Kelley's question, stripped down, is a question about this layer too: a test suite can only verify the world it has seen. So the suite written for Zig is enough to verify the first three layers and not the fourth — he was right to ask, but what he was asking was Spolsky's question.
So the line “never rewrite from scratch,” in 2026, should probably read:
Rewrite if you like, but don't switch over in one go. Don't throw the old code away — it stays, as the referee.
7. Epilogue
Netscape rewrote for three years, and by the time it was done, the market was gone. Bun rewrote for 11 days, and by the time it was done, Bun 1.4 shipped on schedule. Twenty-six years on, “the single worst strategic mistake” lands as a $165,000 bill.
But one thing hasn't changed: that 1%. It was never in the code, and never in the tests; in 2000 it hid inside some computer with no IE installed, and in 2026 it hides inside some PDF a customer uploaded that nobody has ever seen. AI can carry 535,000 lines across in 11 days, patches and all — what it can't carry is whatever was never written down. And that is exactly why I have come to believe that a high-quality test suite is now worth more than the code itself. Behind every test is a real hole someone actually fell into — a race condition, an edge case — and those holes are the one thing today's AI cannot generate with a single prompt. But given a test suite like that, the same software rewritten with AI on a new architecture or a new language will, more likely than not, come out a good deal better than the original.
Spolsky's essay was titled “Things You Should Never Do.” Twenty-six years later, AI does that forbidden thing dozens of times a day.
For people who write code, this is probably the best of times: anything you don't like the look of can be torn down and built again. It is also the worst of times: the faster you tear it down, the less time you have to find out what it was you threw away.